Crystal Clear Memories
Computer Vision
3D GenAI
Automated transformation of photos into 3D memorial keepsakes using a hybrid of classical computer vision and 3D generative AI.

NDA

 Services
 Industry
 TECHNOLOGIES USED
 Team
 Duration
 Location
The project set out to solve a key challenge in paediatric speech therapy: automatically identifying and tracking pronunciation mistakes without constant therapist involvement. The goal was to develop an AI system that detects mispronounced phonemes in real time, handles non-linear speech patterns, and delivers feedback as accurately as – or better than – a trained therapist. But children’s speech brings a unique set of challenges:
Children’s pronunciation changes as they grow, making phoneme boundaries inconsistent and difficult for traditional models to interpret.
Regional and individual pronunciation differences required the model to handle a wide range of phonetic variations.
Sessions often take place outside ideal recording conditions, with background noise, interruptions, or low-quality microphones.
Few existing datasets capture the variety of children’s voices and speech errors needed to train accurate recognition models.
We brought the vision to life through a multi-stage approach, from research and model selection to dataset creation and deployment. Each step addressed specific technical and data challenges while aligning with therapy needs. Using advanced speech recognition, phoneme-level training, and a custom child speech dataset, we built an AI system that delivers reliable, actionable feedback even in noisy, real-world environments.
The client’s vision was clear: automate pronunciation correction for children. But traditional speech recognition models weren’t designed for the nuances of kids’ speech, especially with accents, articulation variability, and noise.
This gave the project a clear path forward and the confidence that the goal was technically achievable.
Wav2Vec 2.0 had strong potential, but it needed careful fine-tuning. Children’s speech is less structured and more variable than adult audio, which makes direct transcription difficult.
The result was a fine-tuned model capable of understanding real-world, imperfect children speech.
Data availability was a critical roadblock. Existing datasets lacked both the quantity and diversity needed for children’s phoneme-level speech.
The dataset became the foundation that enabled real-world accuracy rather than just lab success.
With the model trained and validated, we moved into deployment, focusing on usability, monitoring, and production-readiness.
This collaboration demonstrated how AI and computer vision can bring lab-level insights into users’ pockets, redefining how personal health can be tracked and understood.

No vague promises. No pressure. Just a real conversation with our technical leadership to understand your needs and explore the best next steps.
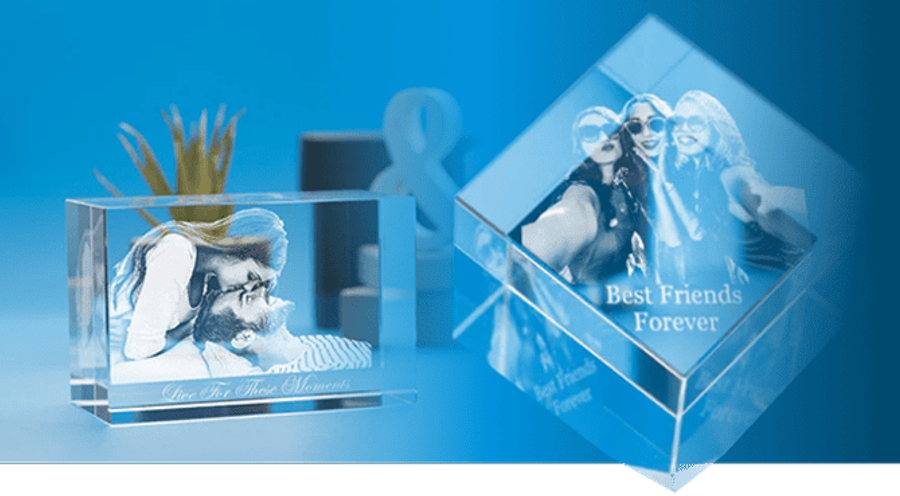
Automated transformation of photos into 3D memorial keepsakes using a hybrid of classical computer vision and 3D generative AI.
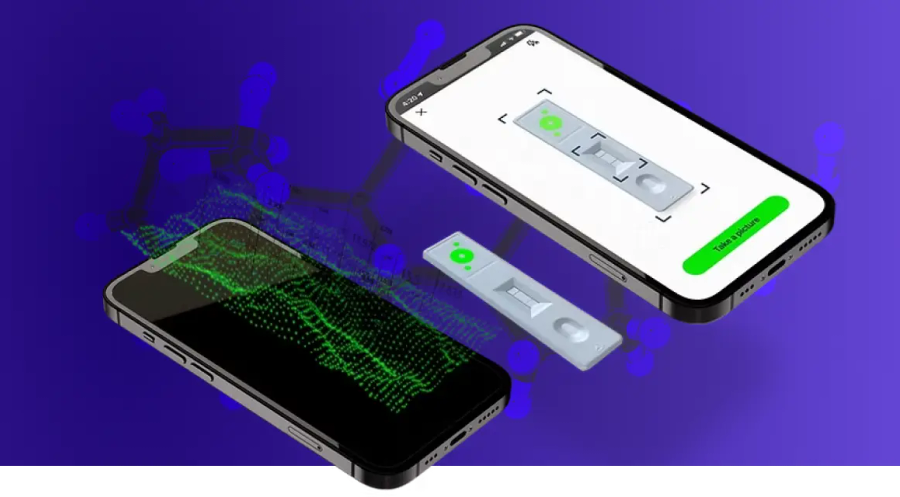
Hormone tracking application powered by Computer Vision with 93%+ accuracy in real-life conditions.